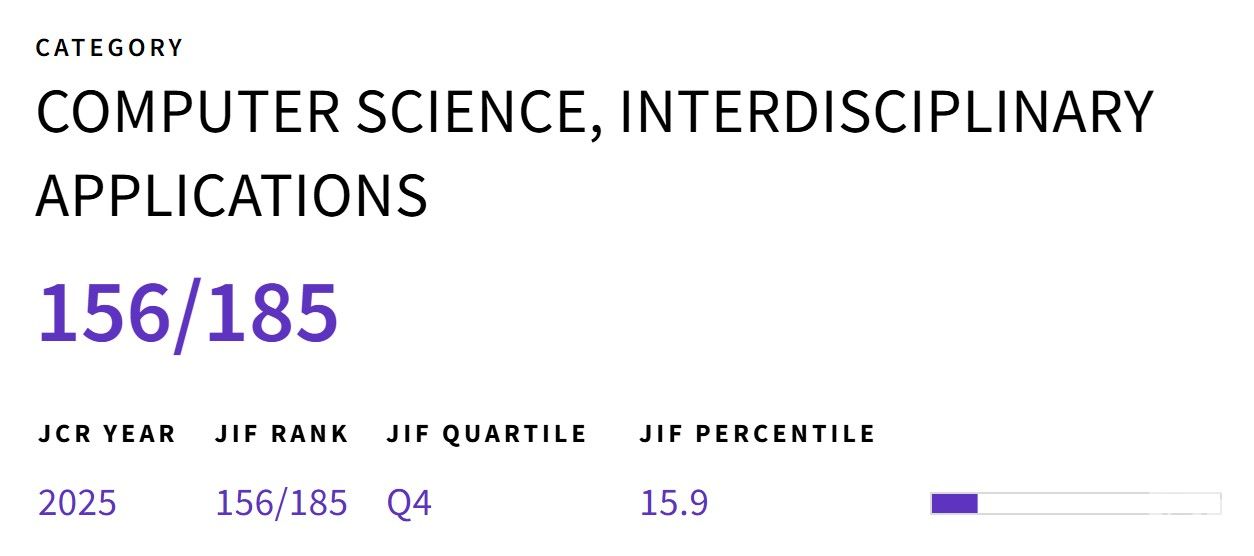
2025
doi: 10.12720/jait.16.2.233-242
Benchmarking Open-Source Large Language Models on Code-Switched Tagalog-English Retrieval Augmented Generation
Aunhel John M. Adoptante1,* ,
Jasper Adrian Dwight V. Castro1 ,
Micholo Lanz B. Medrana1 ,
Alyssa Patricia B. Ocampo1 ,
Elmer C. Peramo1 ,
Melissa Ruth M. Miranda2
- 1Department of Science and Technology, Computer Software Division, Advanced Science and Technology Institute, Diliman, Quezon City, Philippines
- 2Pamantasan ng Lungsod ng Maynila, Intramuros, Manila, Philippines
- Manuscript receivedAugust 28, 2024
- revisedSeptember 30, 2024
- acceptedNovember 11, 2024
- publishedFebruary 17, 2025
Abstract
Code-switching, the alternation between languages within a sentence or discourse, poses significant c hallenges in Natural Language Processing (NLP). Effective NLP systems must employ advanced modeling techniques to accurately process and generate code-switched text, capturing the linguistic nuances and contextual dependencies. This study evaluates five open-source Large Language Models (LLMs)—Mistral, SeaLLM, Falcon, Phi-3-mini, and Gemma—on their perfor-mance with code-switched Tagalog-English (Taglish) queries in a Retrieval-Augmented Generation (RAG) task. Mistral and SeaLLM outperformed the others in generating contextually grounded and relevant answers, attributed to their advanced architectures and extensive multilingual training data. In con-trast, Falcon, Phi-3-mini, and Gemma struggled with effective code-switching handling. The models performed best on En-glish queries, followed by Taglish, with the lowest performance on Tagalog queries, highlighting the need for more balanced training data for low-resource languages. Additionally, models retrieved context better from .pdf documents compared to .txt files. Future research should focus on analyzing language composition in datasets, investigating real-world code-switching behavior, and studying the effects of code-switching on model understanding to enhance NLP accessibility for underrepresented languages.
Keywords
- Large Language Models (LLM)
- code switching
- retrieval augmented generation
How to Cite
Aunhel John M. Adoptante, Jasper Adrian Dwight V. Castro, Micholo Lanz B. Medrana, Alyssa Patricia B. Ocampo, Elmer C. Peramo, and Melissa Ruth M. Miranda, "Benchmarking Open-Source Large Language Models on Code-Switched Tagalog-English Retrieval Augmented Generation," Journal of Advances in Information Technology, vol. 16, no. 2, pp. 233-242, 2025. https://doi.org/10.12720/jait.16.2.233-242
Copyright & License
Copyright © 2025 by the authors. This is an open access article distributed under the Creative Commons Attribution License which permits unrestricted use, distribution, and reproduction in any medium, provided the original work is properly cited (CC BY 4.0).